Adding a Node Can Move 89% of Your Keys. Consistent Hashing Stops It
When a cluster grows by one machine, most routing code does the naive thing. Hash the key, divide by the node count, take the remainder. It works until the autoscaler adds a node. The divisor changes, and the remainder for almost every key points somewhere else. For a cache, that is a miss storm. For a stateful shard, it is a data migration nobody scheduled.
The modulo trap
The math is unforgiving. If a key's owner is hash(key) % N, and N goes from 8 to 9, a key keeps its owner only when both divisions agree. Over a large hash space that holds for about one in nine keys, so roughly 89 percent change owner. The general form is N over N+1 when you add a single node, and it climbs toward 100 as the cluster grows. Nearly the whole warm set evaporates in the same instant the new box starts taking traffic.
The ring
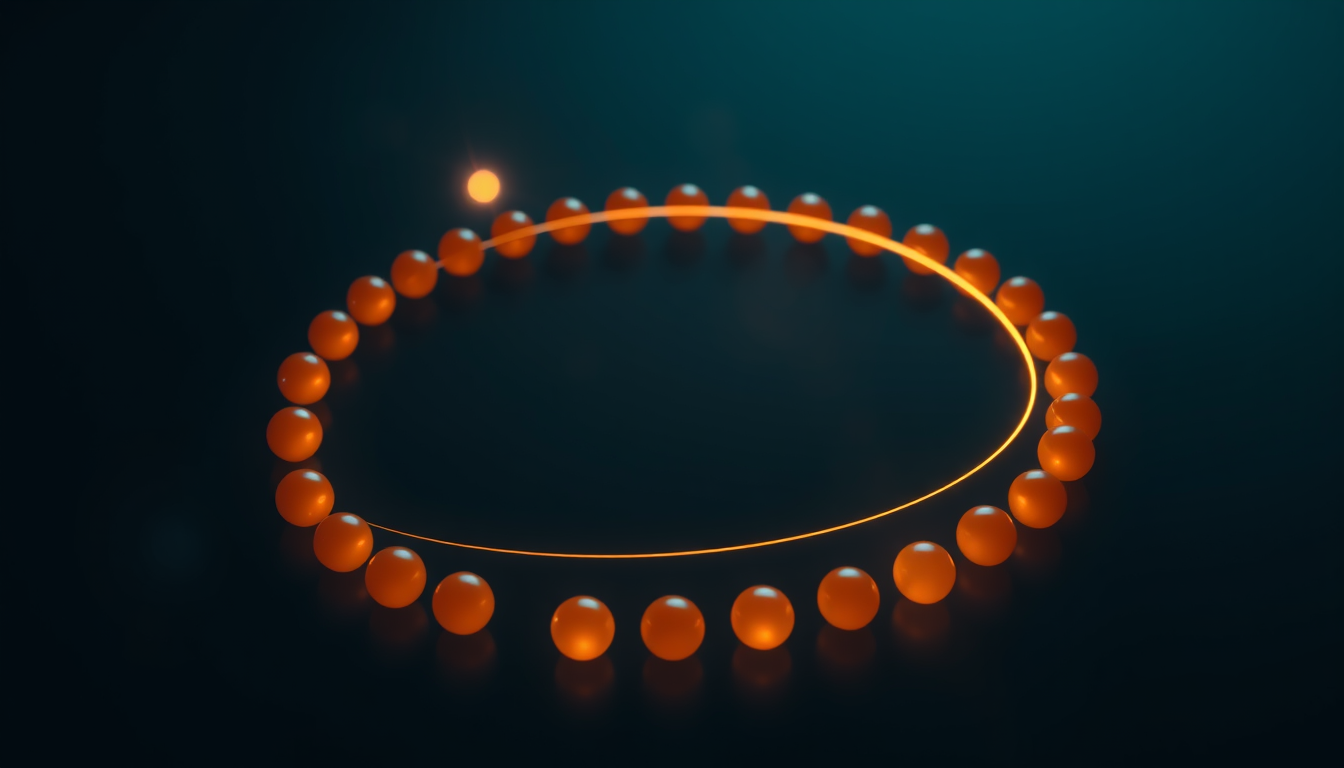
Consistent hashing changes what you hash. Both the keys and the nodes get mapped onto a ring, a circle numbered from 0 up to 2 to the 32nd power. A key's owner is the first node you meet walking clockwise from the key's position. Now add a node: it claims the arc between itself and the node just counterclockwise of it, and only keys in that one arc move. Everything else keeps its owner. That is the entire trick, and it is why the Karger ring underpins Dynamo, Cassandra, and Redis Cluster.
Virtual nodes, and the 16x cut
A bare ring with four nodes is a mess. Four random points on a circle do not split it into four equal arcs; one node can claim a third of the ring while another gets a sliver. The fix is to give each physical node many tokens, usually a hundred to two hundred and fifty, scattered across the circle. Each machine then owns a few hundred tiny arcs, and the law of large numbers smooths the load. When a node dies, its keys spread across many successors instead of dumping onto one unlucky neighbor. That knob is not settled. For years Cassandra defaulted to 256 tokens per node. Cassandra 4.0 cut that to 16, because 256 randomly placed tokens were hurting availability and slowing repair. The exact count is a measured tradeoff, not a constant to copy from another cluster.
The flaw vnodes do not fix
Here is the part that still bites. Virtual nodes balance the count of keys per node, not the traffic. A viral key can carry a thousand times the requests of an ordinary one, and consistent hashing faithfully sends every one of those requests to the single node that owns that point. The owner saturates while the rest of the ring sits idle. I have watched a cache tier do exactly this: the ring was balanced by key count, one partition carried half the query traffic, and the node fell over with headroom everywhere else. A small in-process cache in front of the store catches the hottest keys before they hit the network at all. For genuinely heavy write keys, the honest answer is to change the query model: time-bucket the data or split the partition key.
Bounded-load consistent hashing
Google published a clean answer in 2017, consistent hashing with bounded loads, from Mirrokni, Thorup, and Zadimoghaddam. You set a per-node capacity slightly above the average load. When you place a key you walk clockwise to the first node that is not already at capacity, not the first node period. Overflow spills to the neighbors, and the guarantee is that every node stays under the cap while the churn on add and remove stays bounded. You get the ring's cheap rebalancing plus a hard ceiling on how overloaded any one node can get. HAProxy implements it. In 2025 the KubeAI project reached for the same idea to route LLM inference: a prompt with a long shared prefix wants to land on the replica that already has that prefix sitting in GPU memory. A technique that fixed a load balancer in 2017 is now steering inference to the card with the right cache.
Picking a scheme
Modulo hashing is fine, and I would not overthink it when the node count never changes. Redis Cluster is exactly that case: it shards across 16,384 slots and maps those slots to nodes through a separate table, so the modulus stays constant forever and scaling reassigns slots rather than keys. Reach for the plain ring when you need ownership ranges and multiple replicas across a membership that changes. Add vnodes whenever the node count moves and your hardware is uniform. Reach for bounded loads the moment request skew is real. Rendezvous hashing is the quiet option for small, mostly static clusters where the clients already know the full node list.
I pick the scheme by asking two questions: does the node count change, and does any single key carry outsized traffic? If both are yes, skip straight to bounded loads. If neither is, you probably do not need the ring at all.
Comments